
Monte Carlo: one price series, 31 checks
The case. One price series went in: 250 daily closes from a PDF price file, 249 log returns, for a single asset, plus one market index for the regression. Everything else is computed from it — annualized volatility, log drift, the regression, and a one-year-ahead distribution simulated with 10,000 paths from seed 20250101. The limits sheet treats it as one asset and one sample: no portfolio, no second series, no out-of-sample test. A worked CSV import of a return series is in the CSV/MA10 walkthrough. This is a synthetic case for method demonstration, not investment, tax or legal advice.
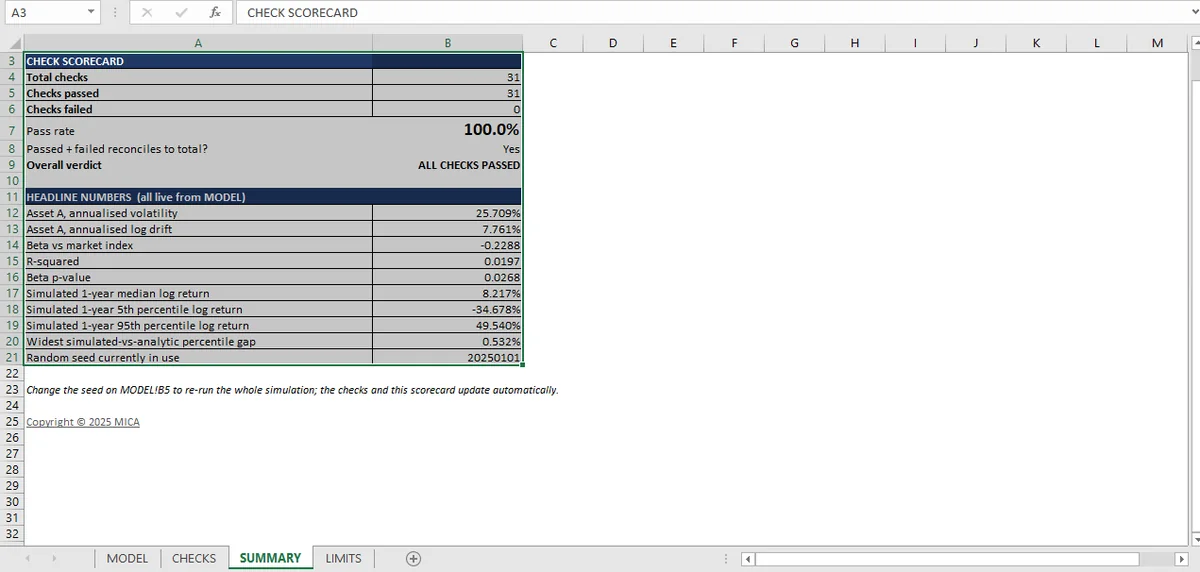
One price series, 249 returns, ten thousand seeded paths. Volatility is 25.71%, beta is −0.229 with an R-squared of 0.0197, and five simulated percentiles match the lognormal formula to within 0.0053.
| Measure | Result |
|---|---|
| Observations | 250 prices, 249 log returns |
| Annualized volatility | 25.71% |
| Annualized log drift | 7.76% |
| Beta vs the market index | −0.229 |
| R-squared | 0.0197 |
| Beta p-value | 0.0268 |
| Simulated paths | 10,000 |
| Seed | 20250101 |
Thirty-one checks back the workbook. All pass.
The simulation agrees with the assumption it was built on. That is a consistency result, not a validation of the assumption.
What thirty-one checks show
The checks fall into seven groups; the first four carry the main argument, and the remaining thirteen cover the probability tree, the regression's reported statistics and the moment comparisons.
The data (3 checks). 249 log returns from 250 prices, no zero or negative closes anywhere, dates strictly increasing. These are trivial and they are the first things that break: a sorted-out-of-order series silently changes every return and every statistic downstream. The cleaning side of that series is in the data-cleaning guide.
The identities (4 checks). Annualized volatility equals daily standard deviation times the square root of the trading year; beta equals correlation times the ratio of the two volatilities; R-squared equals correlation squared; the p-value lies in [0,1]. Each is a relationship that has to hold regardless of the data, so a failure is always an implementation error.
The simulation (7 checks). The seed is a non-zero integer, so the run is reproducible. The path count is 10,000. The random draws have mean zero and standard deviation one. The simulated mean and standard deviation match the analytic drift and volatility. The percentiles match the analytic lognormal percentiles.
The ranking tests (4 checks). The percentile ladder (P5 below P25 below P50 below P75 below P95) holds end to end, for both the simulated and the analytic distribution.
Why a simulation needs an analytic answer
A Monte Carlo is only checkable if you know what it should produce. Here the answer is a lognormal distribution: given the drift and volatility, the 5th, 25th, 50th, 75th and 95th percentiles one year ahead are closed-form.
| Percentile | Simulated | Analytic | Gap |
|---|---|---|---|
| 5th | −0.3468 | −0.3453 | 0.0015 |
| 25th | −0.0905 | −0.0958 | 0.0053 |
| 50th | 0.0822 | 0.0776 | 0.0046 |
| 75th | 0.2535 | 0.2510 | 0.0025 |
| 95th | 0.4954 | 0.5005 | 0.0051 |
The widest gap is 0.0053 in log-return terms, which is the sampling error of 10,000 paths, not a modeling error. That is the check that makes the simulation credible: the model does not merely produce a distribution, it produces the distribution the theory says it should.
The beta that is significant and explains nothing
Beta is −0.229 with a p-value of 0.0268, statistically significant at the 5% level. R-squared is 0.0197, which means the market index explains 2% of the variation in this asset's returns.
Both facts are true and they point in opposite directions for anyone reading them quickly. A significant beta says the estimate is unlikely to be zero; a 2% R-squared says the relationship is too weak to be useful for explaining returns. The workbook reports both, adjacent, which is the only honest way to present a regression on 249 observations.
The rest of the series
Returns and time value is the data and the three basic statistics. The probability tree is the smallest object with probabilities that have to add up. The Monte Carlo is the 10,000-path run against its closed form. The regression is the beta that is significant and explains nothing. The efficient frontier is about constraints on an optimizer this workbook does not contain. Out-of-sample testing is the test that is missing. The integration article is how the 31 checks fit together.
What the sample cannot tell you
The limits sheet states them, and four matter.
One asset, one series. No portfolio, no second asset, no covariance matrix. Whatever the simulation says about Asset A says nothing about a portfolio of them. The portfolio layer that consumes a covariance matrix is the portfolio optimizer.
The distribution is assumed, not tested. Returns are modeled as normal in log terms. The workbook does not test the price series for normality, autocorrelation or volatility clustering. It assumes lognormal and then checks the simulation against that assumption.
No out-of-sample test. Every statistic is computed on the full 249 observations. Nothing is held back, so nothing establishes that the model predicts.
The seed makes it reproducible, not correct. A seeded generator means the same paths come out every time. It does not mean the paths are drawn from the right distribution. The percentile comparison is what tests that.
The useful summary is the one the four groups already give: the data is clean, the identities hold, the simulation reproduces its analytic answer, and the regression is statistically significant while explaining almost nothing. Three of those are checks; the fourth is a judgement the workbook hands to the reader.
The seed sits in a cell in Mica, which lets the whole simulation be re-run and re-checked against the same paths.
Frequently asked questions
How many Monte Carlo simulations should I run?
Enough that the statistic you report has converged; 10,000 paths is a common starting point. This workbook uses 10,000 from a seed stored in a cell (20250101), so the same run can be repeated exactly.
How do you validate a Monte Carlo simulation?
Compare it with a case that has a closed-form answer, then check convergence as paths increase and repeatability from a fixed seed. Here the 5th to 95th percentiles are within 0.0053 of the lognormal closed-form values.
Is a statistically significant beta useful if R-squared is low?
Significance says the slope is unlikely to be zero; R-squared says how much of the variation it explains. Here beta is significant at p = 0.0268, but R-squared is 0.0197, so the market explains about 2% of the variation and the beta is a poor predictor even though it is real.
Why seed a Monte Carlo simulation?
A seed makes the run reproducible: the same seed and the same draws give the same answer, so a check can be re-run and audited. Nothing in this simulation uses volatile RAND().